robandersonnz: Has the Fleet Working on Improving Qwen3.8 27B 8-bit on M1 Ultra Mac Studio Running mlx-omarchy
@robandersonnz · Mac Studio M1 Ultra
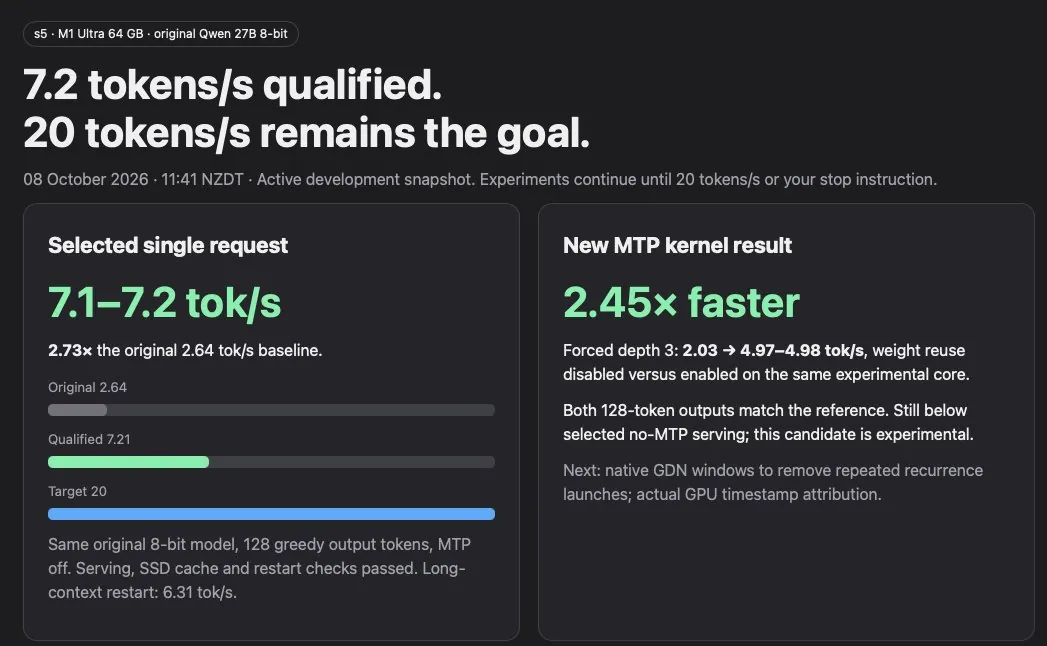
robandersonnz says they have the fleet working on improving Qwen3.8 27B 8-bit on M1 Ultra Mac Studio running mlx-omarchy by JoshuaSWarren: "Started at 2.6 tok/s and up to 7.1 Tok/s after a few hours!"; the still is a page headed "s5 · M1 Ultra 64 GB · original Qwen 27B 8-bit" with "7.2 tokens/s qualified." and "20 tokens/s remains the goal.", a "Selected single request" card at "7.1–7.2 tok/s" reading "2.73× the original 2.64 tok/s baseline." with "Original 2.64", "Qualified 7.21", and "Target 20" bars, and a "New MTP kernel result" card reading "2.45× faster".