Themes are applied in this browser only. “Follow” reads
~/.local/state/omarchy/current with your permission and tracks
omarchy theme set live; nothing is uploaded.
robandersonnz: Has the Fleet Working on Improving Qwen3.8 27B 8-bit on M1 Ultra Mac Studio Running mlx-omarchy
robandersonnz says they have the fleet working on improving Qwen3.8 27B 8-bit on M1 Ultra Mac Studio running mlx-omarchy by JoshuaSWarren: "Started at 2.6 tok/s and up to 7.1 Tok/s after a few hours!"; the still is a page headed "s5 · M1 Ultra 64 GB · original Qwen 27B 8-bit" with "7.2 tokens/s qualified." and "20 tokens/s remains the goal.", a "Selected single request" card at "7.1–7.2 tok/s" reading "2.73× the original 2.64 tok/s baseline." with "Original 2.64", "Qualified 7.21", and "Target 20" bars, and a "New MTP kernel result" card reading "2.45× faster".
JoshuaSWarren says "Your old Mac got a second life with Omarchy. Give it a second job in a cluster." GLM-5.3 is 753B params, 216 GB, and it ran as one endpoint across a Mac Studio, three MacBook Pros and a Dell laptop, on Omarchy: "Slow, but the full model runs - not a quant." They link joshuaswarren/omarchy-cluster, and in a follow-up reply say performance improvements to speed it up are coming next, as well as pulling in more interface methods, and eGPU support: "Right now it can use direct Thunderbolt links or the fastest network link you can give it, but I want to pull in @ashxhart's MCDMA and other methods too."
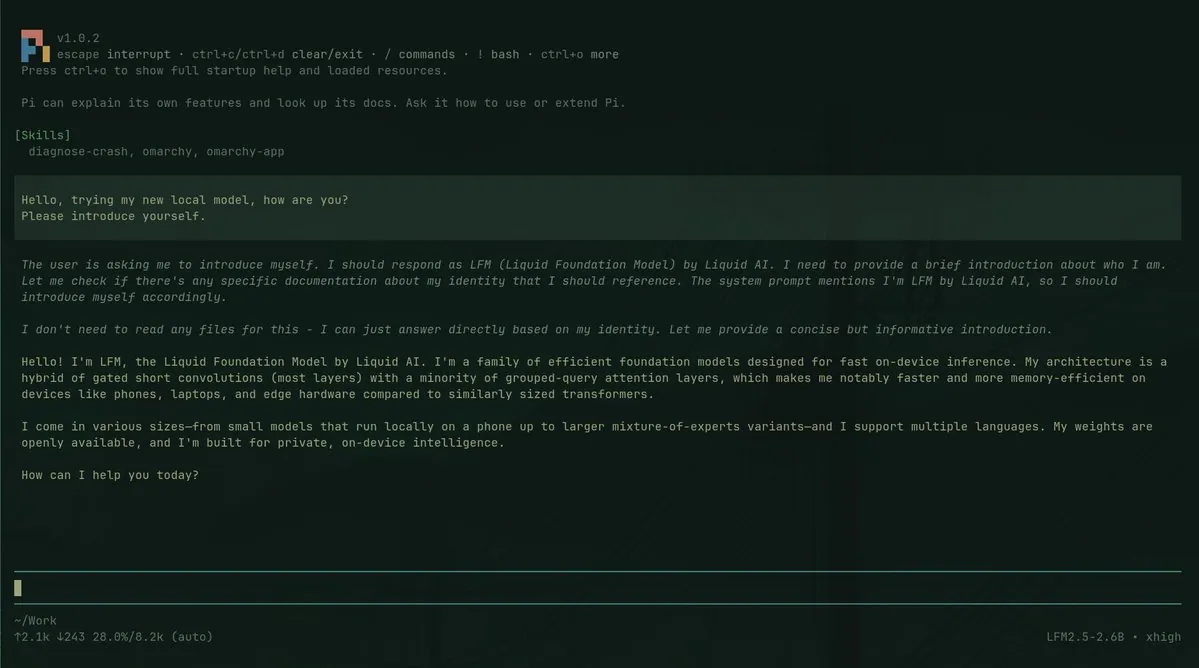
EricF_Off runs a first local AI model on a tiny Omarchy Geekom A8 box and credits 0xSero for the plugin that made setup easy; the still is a green-on-dark Pi chat where skills list diagnose-crash, omarchy, and omarchy-app, the user asks the new local model to introduce itself, and the reply presents LFM, the Liquid Foundation Model by Liquid AI, with a footer showing LFM2.5-2.6B · xhigh.
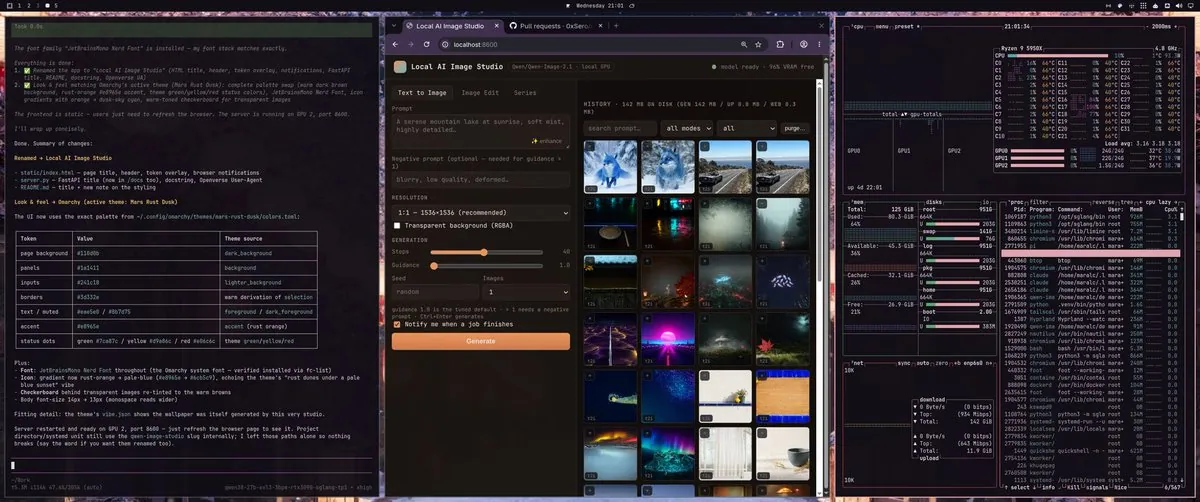
maralcbr has been grinding the Omarchy Local AI from 0xSero on an Omarchy Franken GPU (3x 3090), with Qwen 3.8 27B on two GPUs and Qwen Image 2.1 on another, and with the integrated Pi quickly created a local image generation engine and website, a local Omarchy Theme Generator, and Tailshare QR Code Phone AI Chat; the screenshot shows a three-pane Omarchy desktop with a Local AI Image Studio, a notes pane, and btop on a Ryzen 9 5950X.